Imagine drawing ten points on paper and fitting two curves through them. One bends gently. The other twists several times between neighboring points. Both get all ten answers right. Now cover up an eleventh point and ask where it lies. The two predictions may be far apart.
When the same observations admit many explanations, what gives us reason to trust one more than another?
We can ask that question three ways. Once we have seen the data, how much weight should we give each explanation? How well will predictions made with those weights hold up on fresh observations? And if we leave the choice to an algorithm that starts at random and adjusts its parameters one step at a time, where will it actually end up? Free energy appears in all three questions, playing a different role in each.
From a single curve to a distribution over curves
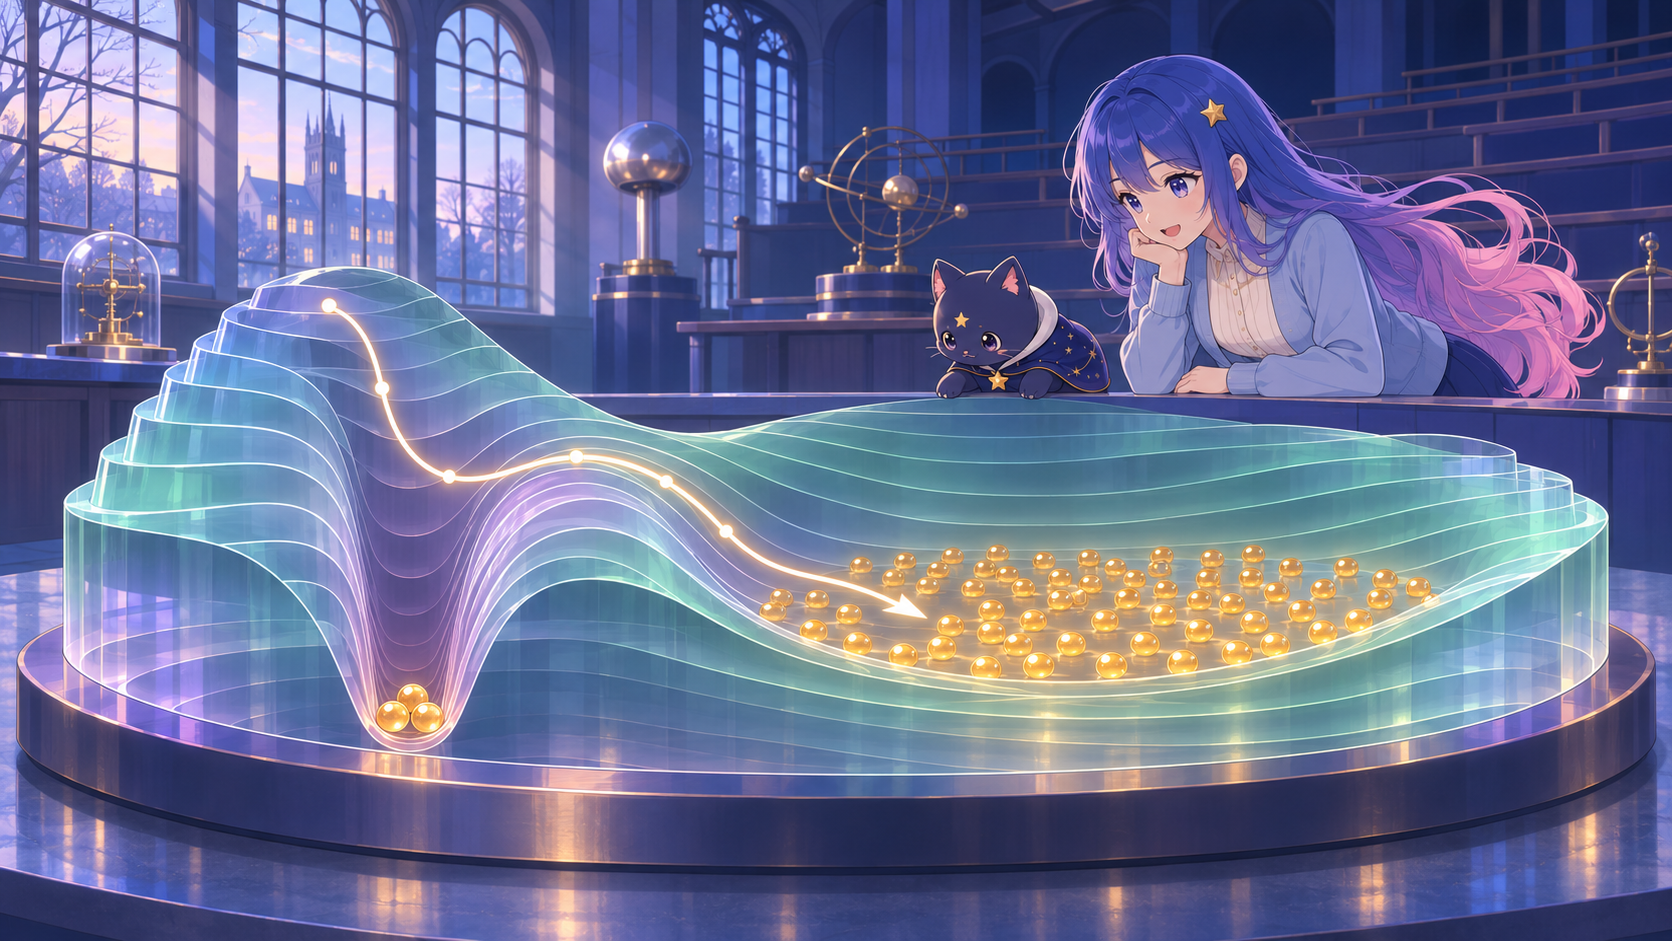
Picture each model as a point on a landscape, with its training loss as its elevation. We can compare two points by comparing their heights. To assign probability to a whole valley, we also need to know how much weight we initially gave that region. A shallow valley with room for many curves that fit about equally well can end up carrying more weight than a deep, narrow one.
Let be our training set, the parameters, and the average training loss. Before seeing these data, we assign weights to the parameters using a prior . After seeing them, we describe our revised judgment by a distribution . At temperature , the free energy is
The first term asks a simple question. If we draw a curve from , what training error should we expect on those ten points? The KL divergence in the second term measures how far the update takes us from the prior. Favoring a family of curves that already had substantial prior weight costs relatively little information. Concentrating almost all the weight on previously rare solutions takes a larger improvement in fit to justify. The temperature sets the exchange rate between that improvement and its information cost.
Whenever the normalizing constant is finite and positive, the distribution minimizing free energy has an explicit form
This is the Gibbs distribution. Each parameter value starts with its prior weight, which is then adjusted according to its loss. Of two values with equal prior weight, the one with lower loss receives more weight. The same loss difference matters more at lower temperature. Substituting the Gibbs distribution into the definition gives the identity
The first term on the right is independent of . The second is nonnegative and vanishes when . Even when the full Gibbs distribution is intractable, we can search over a manageable family, such as Gaussians. Within that family, minimizing free energy amounts to finding the approximation with the smallest . This gives one formulation of variational inference.
What, then, is the width of a valley? If the loss throughout a region is roughly constant at , its contribution to is approximately . The corresponding regional free energy is about . Here width measures the prior mass assigned to the region. A sketch of the valley floor alone tells us little about how accurately a curve will predict the eleventh point.
Bayesian inference fixes the temperature
So far we have been free to choose both the loss and the temperature. Ordinary Bayesian inference makes a particular choice. Treat the inputs as given, assume the labels are conditionally independent given the inputs and parameters, and take the average negative log-likelihood as the loss. Then
By Bayes’ rule the posterior is proportional to the prior times the likelihood, or . Comparing this with the Gibbs distribution gives . The factor of comes from a small bookkeeping detail. Training loss is the mean of the individual losses, while the log-likelihood of the full dataset is the sum of the individual log-likelihoods.
At this temperature, is the model evidence, also called the marginal likelihood. Imagine two ways of generating curves, each with its own parameters and prior. Comparing best fits means picking the strongest curve from each family. Comparing evidence asks what likelihood each family assigns to the observed data on average when we draw curves from its prior. A family may contain one exceptionally good fit. If very little prior mass lies near it, that curve may contribute little to the evidence for its family.
Under the usual regularity conditions, a Laplace approximation to the evidence integral gives the leading terms of the Bayesian information criterion (BIC). This requires ample data, fixed parameter dimension, a smooth and nondegenerate likelihood peak, and positive prior density there
Here is the maximum likelihood estimate and is the parameter dimension. The complexity penalty emerges from integrating over parameters. Its form depends on the local geometry just described. In a deep network where many parameter settings represent the same predictor, inserting the raw parameter count into this formula calls for care.
How do more examples rule out the wrong explanations?
Set aside our curves for a moment and consider a classification problem with a known answer. A teacher holds a fixed weight vector whose entries can each take only the values or . For every standard Gaussian input, the teacher labels the example by the sign of its weighted sum. The student knows how the labels are made but does not know the weights. It starts with all binary weight vectors and keeps every candidate that answers all the training questions correctly. This is a teacher–student Ising perceptron.
The overlap measures how closely a student’s weights match the teacher’s. On a fresh Gaussian input, the student’s probability of error is . The two are related by
When , the weights agree exactly. When , the weight vectors are orthogonal. The student could still have answered every training question correctly, yet its chance of getting a new question wrong is . With a uniform prior on weight vectors, an individual wrong candidate may carry little weight while the multitude of wrong candidates carries considerable weight in total. For a candidate with population error , the probability of answering all independent training questions correctly just by chance is . How quickly those odds fall depends on how closely the candidate matches the teacher.
Write for the number of examples per parameter. In the high-dimensional limit of this model, when crosses a critical value, a typical student’s population error jumps from a positive value to zero. This is a learning phase transition. On either side of the transition, every surviving candidate already answers the training questions correctly. It is their performance on new questions that changes abruptly. We are back at the eleventh point. Györgyi’s study of the binary perceptron
How does free energy bound error on new examples?
In the perceptron example, knowing the input distribution allowed us to calculate the student’s chance of making a mistake. Usually we have only the training set. We must distinguish the training loss from the population loss . Here is a fresh example drawn from the same distribution , and is the loss on a single example.
PAC-Bayes gives us a way to bound the latter using the former. Suppose the training examples are independent and identically distributed, individual losses lie in , and we fix the prior , temperature , and confidence parameter before seeing the training set. Then, with probability at least over the training sample, the following inequality holds simultaneously for every distribution with finite KL divergence from the prior
To read the left-hand side, imagine drawing parameters from the learned distribution and using them to predict a new example. The free energy on the right uses the same loss and already accounts for both training performance and the information cost of departing from the prior. The remaining terms account for confidence and finite-sample fluctuations. Because the bound holds for every admissible at once, we can choose after seeing the data. With , the 95% refers to how often the guarantee holds across repeated draws of the training set. It says nothing directly about the percentage of new questions the model answers correctly.
Two restrictions are worth keeping in mind. Ordinary negative log-likelihood can be unbounded, so the Bayesian loss from earlier may fall outside the bounded-loss assumption here. With a continuous prior, concentrating at a single parameter value can also make the KL divergence infinite. A useful guarantee for a single trained model generally requires randomization, quantization, or a separate argument. Choosing the prior or tuning the temperature on the same data also incurs a selection cost. Alquier’s introduction to PAC-Bayes bounds
We can also study the learning algorithm directly. Denote its output parameters by . The mutual information measures the statistical dependence of that output on this particular training set. Under the same independence and bounded-loss assumptions, we have
The expectation on the left averages over both the draw of the training set and the algorithm’s own choices. It controls the average generalization gap. A model that learns nothing can have a tiny gap simply by performing equally poorly on training and fresh examples. To find out whether its predictions are useful, we still need the level of the loss itself. Xu and Raginsky’s mutual-information bound
When does training actually decrease free energy?
We can now write down an ideal distribution and bound its population risk. An actual training run, however, begins at one initial point and takes a finite number of steps. Why should it approach the distribution we just calculated?
Ordinary gradient descent updates its parameters by , where is the learning rate. Stochastic gradient descent (SGD) estimates the full gradient from a minibatch of size . Changing the batch can change the direction of descent even at the same point. Take a small step size, sample independently within a batch, and approximate gradient noise as Gaussian and isotropic with position-independent strength. Under these assumptions a Langevin equation can approximate the parameter dynamics
Here is Brownian motion, and is the scalar used to approximate the single-example gradient covariance. The first term moves the parameters downhill. The second spreads out trajectories across training runs. In this approximation a larger learning rate or a smaller batch gives a higher effective temperature. This temperature comes from the update rule. The Bayesian temperature came from the likelihood convention, so agreement between the two would require an additional reason.
To retain the influence of the prior at equilibrium, replace the loss in the drift with the potential . For example, a zero-mean isotropic Gaussian prior adds a penalty proportional to the squared parameter norm. Imagine many independent runs of this process. Each trajectory is random, yet the density of the whole ensemble obeys the deterministic Fokker–Planck equation
The first term transports probability toward lower potential, while the second describes diffusion. Keep the prior and temperature fixed. Given a smooth density and suitable boundary conditions, such as zero normal probability flux, free energy evolves according to
The minus sign makes the claim that training lowers free energy precise. A single random step can move uphill in loss, while the free energy of the entire parameter distribution evolving under this equation is nonincreasing. This evolution is a Wasserstein gradient flow. The associated distance measures the cost of transporting one distribution of mass into another. If the equilibrium distribution is normalizable and the process mixes sufficiently, we recover . When the aim is to sample a Bayesian posterior, stochastic gradient Langevin dynamics (SGLD) calibrates the drift and additional noise to the target and uses an appropriate step-size schedule. Welling and Teh’s SGLD paper
Can trajectories keep circling once the distribution is stationary?
This brings me back to a question from an earlier essay. Each time we decode a latent state and encode it again, we observe a displacement . If we treat these displacements as approximations to a continuous velocity field, can we find a potential whose negative gradient gives that field? We are trying to reconstruct the landscape from the motion we observe. Some Thoughts on Potential Functions and Latent-Space Topology
The Langevin model lets us reason in the other direction. First assign a potential to each parameter setting. Its negative gradient gives the drift there. Now consider the ensemble. Average against the density and add the entropic term associated with diffusion. The result is precisely the free energy introduced above. We now have a distribution-level counterpart to a single state’s downhill motion, with a different notion of height at each level. Jordan, Kinderlehrer, and Otto’s derivation of the gradient flow
The circle from the earlier essay makes this distinction tangible. Imagine particles scattered uniformly around a unit circle, each diffusing at random. Now give every particle an additional clockwise drift with the same angular speed . Take a snapshot a while later. In either experiment the density is . Instead, stand at one mark on the circle and measure the net flow across it. With diffusion alone, the two directions cancel on average. With drift, there is a clockwise probability current of . Even persistent circulation can be invisible in a density plot.
This drift also explains why the earlier essay examined closed paths. If clockwise motion were downhill everywhere, a particle completing a lap would end at a lower potential than where it started. Yet a single-valued potential must give the same height at the same point. With the usual metric on the circle, no globally single-valued potential has this drift as its negative gradient.
If I were running the encoding and decoding experiment, I would record both the locations visited and the order of successive states. The first record would show which regions receive frequent visits. The second would let me compare transitions in opposite directions along a suspected loop. Two collections of trajectories could produce similar density maps while circulating in different directions. The time-ordered observations would let us test that possibility.
What survives a finite training run?
Start with time. A valley that should carry most of the equilibrium probability may go unvisited while training stays in its neighbor. Reaching it might require crossing a high-loss ridge or finding a very narrow passage. These are energetic and entropic barriers, respectively. When a thermally activated escape approximation applies, the escape time scales as , where is the free energy barrier. A small increase in the barrier can push the waiting time far beyond the training budget.
Next consider step size. For the one-dimensional quadratic loss with , gradient descent reduces to . Convergence to the minimum from any initial point requires . Beyond the upper limit, each step crosses to the other side of the minimum and lands farther away. In a positive-definite multidimensional quadratic approximation, the steepest direction sets the limit, , where is the loss Hessian. Choosing a learning rate already influences which valleys can stably hold an iterate.
Finally, consider the noise. Actual minibatch noise can be strong along some directions, weak along others, and variable over training. With squared loss, once every training residual is zero, every individual gradient is zero as well. At that point no choice of batch can move the parameters. Other solutions may be close by, but SGD will no longer explore them as constant-temperature Brownian motion would.
We can work this out explicitly in fixed-feature linear regression. Let , and place the training feature vectors in the rows of a matrix . If the number of parameters satisfies and has full row rank, exact interpolation requires and leaves a solution set of dimension . Start ordinary SGD at , use squared loss, and omit weight decay. If the iterates converge to an interpolating solution, it must be
Here denotes the pseudoinverse. The first term is the minimum-norm solution that fits the training data. The second is the projection of the initialization onto the null space of , the directions that leave every training prediction unchanged. Each minibatch gradient is a linear combination of training feature vectors, so no number of steps can alter this component. Zero initialization yields the minimum-norm solution. A random initialization can preserve a different prediction that the training set cannot distinguish. If our eleventh point has a feature component in just such a direction, the difference becomes visible.
This example offers a way into double descent. Fix the sample size and gradually increase the number of features. In some noisy regression problems, test error initially falls as the fit improves. Near the threshold where interpolation first becomes possible, small singular values of the feature matrix let the pseudoinverse amplify label noise, pushing test error back up. Add still more features and there are more ways to interpolate. With suitable features and data distributions, the minimum-norm solution’s test error can fall a second time as the feature count grows. Training error has already reached zero, yet test error continues to change. The limiting-solution formula alone cannot tell us that a particular dataset must exhibit this curve. Belkin and colleagues on double descent
Back to the eleventh point
Looking again at those two curves, I would ask three more specific questions. First, which curves seemed plausible to begin with, and how much reason do ten points give us to change our minds? Second, does the eleventh point come from the same distribution as the first ten? Third, where the data leave the curve undetermined, how will our algorithm draw it? Prior-weighted free energy, generalization bounds, and training dynamics each put one of these questions into a form we can calculate with.
In real deep networks the features themselves change during training. Momentum, learning-rate schedules, and the order of examples also affect the outcome. Some questions are directly testable. Which predictions change when we vary the initialization? With a fixed training budget, which directions can the gradients from different batches actually move the parameters in? Recording these quantities gives us a chance to distinguish the roles of noise, geometry, and initialization when the test-error curve turns.
One more limit comes from the data. The bounds above assume that training and test samples come from the same distribution . If a certain animal always appears against the same kind of background in the training images, a model could achieve low in-distribution error by relying on the scenery alone. Once the background changes, the original guarantee says little about whether the model will still recognize the animal. For an agent, high reward in its training environment, learning the objective we intended, and reliable behavior in a new environment each deserve their own test. Both curves pass through the first ten points. To find out whether the bend between them is justified, sooner or later we have to look at the eleventh.
References
- The Iliad course notes place these ideas in the broader setting of statistical mechanics and learning theory. Physics of Deep Learning
- Géza Györgyi (1990) studies the first-order transition to perfect generalization in a binary-weight perceptron. First-order transition to perfect generalization in a neural network with binary synapses
- Pierre Alquier (2024) surveys the assumptions behind PAC-Bayes bounds and how they can be used. User-friendly introduction to PAC-Bayes bounds
- Aolin Xu and Maxim Raginsky (2017) use mutual information to characterize an algorithm’s average generalization gap. Information-theoretic analysis of generalization capability of learning algorithms
- Chiyuan Zhang, Samy Bengio, Moritz Hardt, Benjamin Recht, and Oriol Vinyals (2017) use random labels to study the fitting capacity of deep networks. Understanding deep learning requires rethinking generalization
- Max Welling and Yee Whye Teh (2011) introduce stochastic gradient Langevin dynamics for approximate posterior sampling. Bayesian Learning via Stochastic Gradient Langevin Dynamics
- Mikhail Belkin, Daniel Hsu, Siyuan Ma, and Soumik Mandal (2019) discuss how test error changes on either side of the interpolation threshold. Reconciling modern machine learning practice and the bias-variance trade-off

If you enjoyed this, leave a comment~